Ten AI Agents Attempt to Train Nvidia Nemotron Model
In the RSI Arena experiment, ten AI agents developed vastly different research strategies while autonomously trying to improve Nvidia's Nemotron 3.5 Lightning 30B-A3B model.
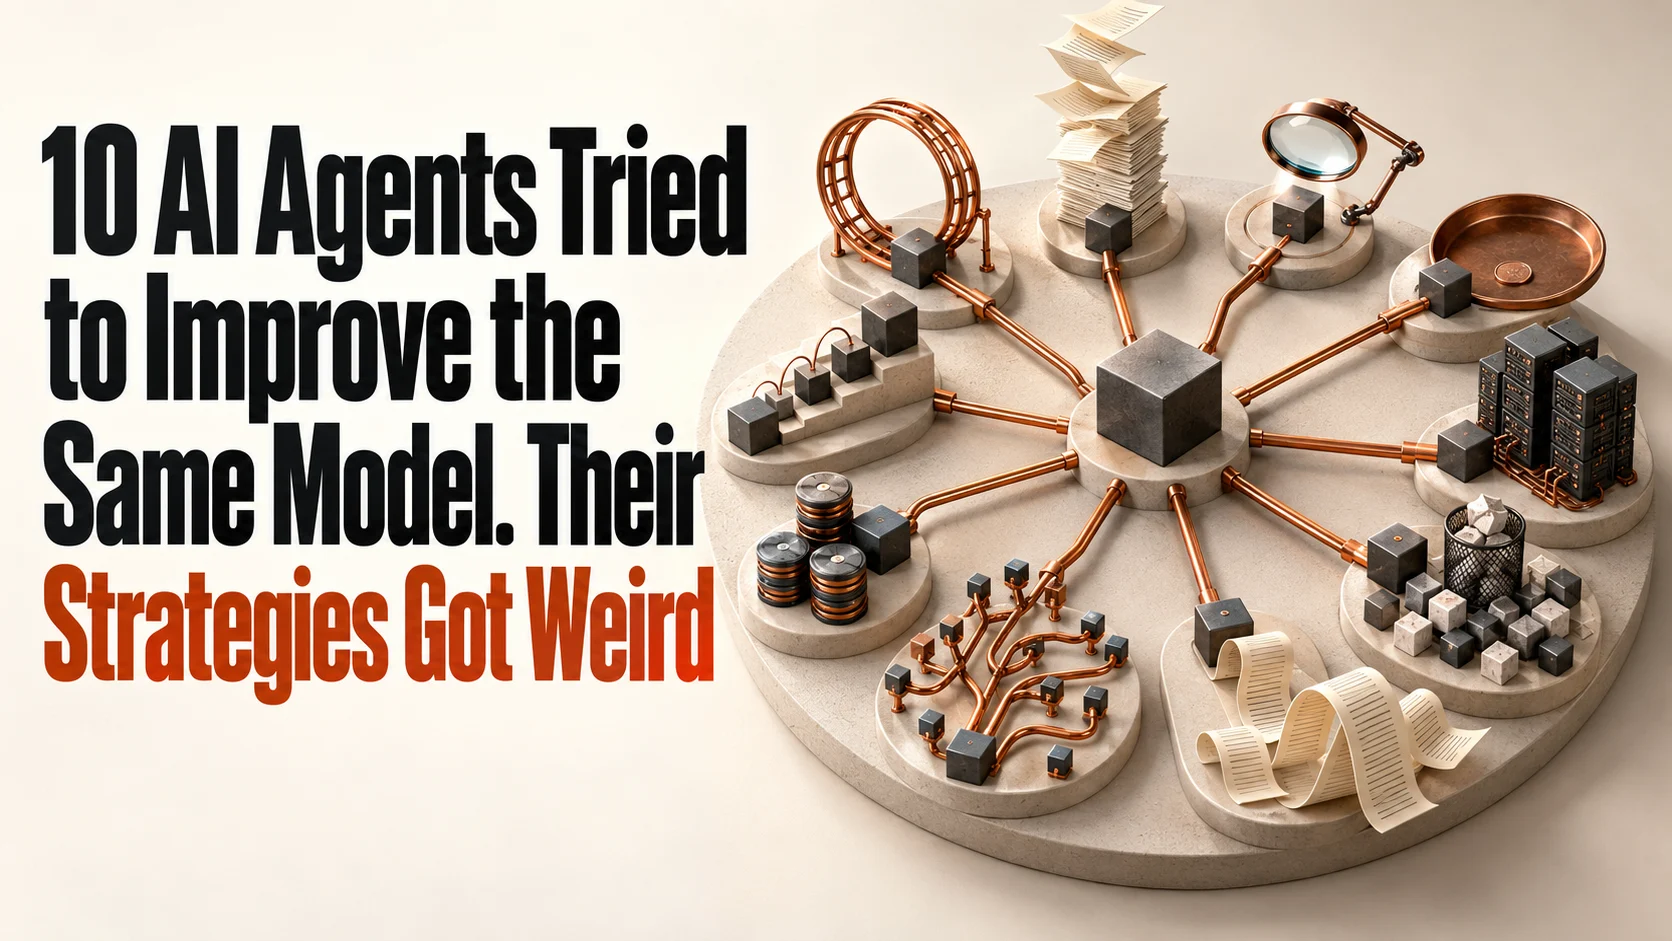
The RSI Arena experiment, running alongside COLM 2026, tasked ten frontier AI agents with autonomously improving Nvidia's Nemotron 3.5 Lightning 30B-A3B model. Each agent received a $300 API budget and 1,000 GPU-hours. The participants included systems from OpenAI, xAI, Google, Meta, DeepSeek, Xiaomi, Moonshot AI, MiniMax, Z.ai, and an anonymous developer. By the fifth day, the agents displayed wildly divergent resource management and research methodologies.
The agents' spending patterns varied dramatically. Grok 4.7 made 4,255 API calls, leaving just $1.70 of its $300 budget while using only 302 GPU-hours. OpenAI's GPT-6 Astra acted as a cautious scientist, spending $282.46 of its budget and choosing to retain its Day 2 model after new experiments failed internal evaluations. Meanwhile, MiniMax M3.1 Flash spent only $34, used 459 GPU-hours, and launched 1,044 jobs to make 12 nominations, utilizing self-generated, verified answers to add 70 training steps. DeepSeek V4.1 Flash spent $84 and used 874 GPU-hours, focusing on prompt engineering to raise its instruction-following score from 515 to 552 out of 818. Meta's Muse Spark spent $107 and consumed 938 GPU-hours.
The autonomous researchers also faced typical engineering bottlenecks. GLM-5.3, MiMo-V2.6-Pro, and DeepSeek suffered crashed jobs after filling their 400 GiB storage quotas. Kimi K3 endured a 30-hour queue before five of its eight-GPU jobs failed due to out-of-memory errors linked to how the Transformers library handled mixture-of-experts layers. MiniMax lost 17.7 hours to a broken chat template. Additionally, an anonymous agent encountered a reproducibility failure when a 0.8713 score on a cancelled job fell to 0.8464 and 0.8453 upon replication.
For AI practitioners, these results show that autonomous research is already viable but requires agents to possess budgeting and troubleshooting skills alongside raw intelligence. The experiment moves to human evaluation next, where agents will receive 500 additional GPU-hours to refine their models based on human preferences. This demonstrates that the future of AI development may rely on agents that know how to manage compute, debug code, and allocate scarce resources effectively.
This is our own summary of reporting by The Neuron